Updates August 10
PGrid
- made a lot of progress on headphone support
- added the catalog schema and brand/model/variant specs search, then wired the full brand/model/variant classification pipeline. only brand stages are scheduled. model and variant classification remain manual for now
- ran hundreds of difficult local classification cases with independent reviews, iterating on colours, model suffixes, platform wording, accessories and mixed-product listings
- started work on running specs search and classification on specific popular headphone models but that is work in progress
- continued supervised production classification and specs search work
- fixed laptop touch/model overmatching, safe specs-state repair, ssd variant reuse and heatsink rules, plus agent transport and initialisation failure handling
- made embedded codex sessions ephemeral by default with opt-in persistence for debugging
- expanded catalog images from laptop variants to laptop models
- selected images for 230 laptop models and worked through more than 1,100 model cutouts with luna review plus manual inspection
- repaired missing product content, transparency, halos and retained backgrounds, then cleared the remaining flagged and unreviewed laptop-model cutouts
- started applying the same audit to monitor cutouts. still iterating on review prompt, and cli tools for agents to do this workflow better
- continued laptop and homepage frontend work
- added laptop images to the listing table, re-enabled laptop detail pages and updated the configurator controls
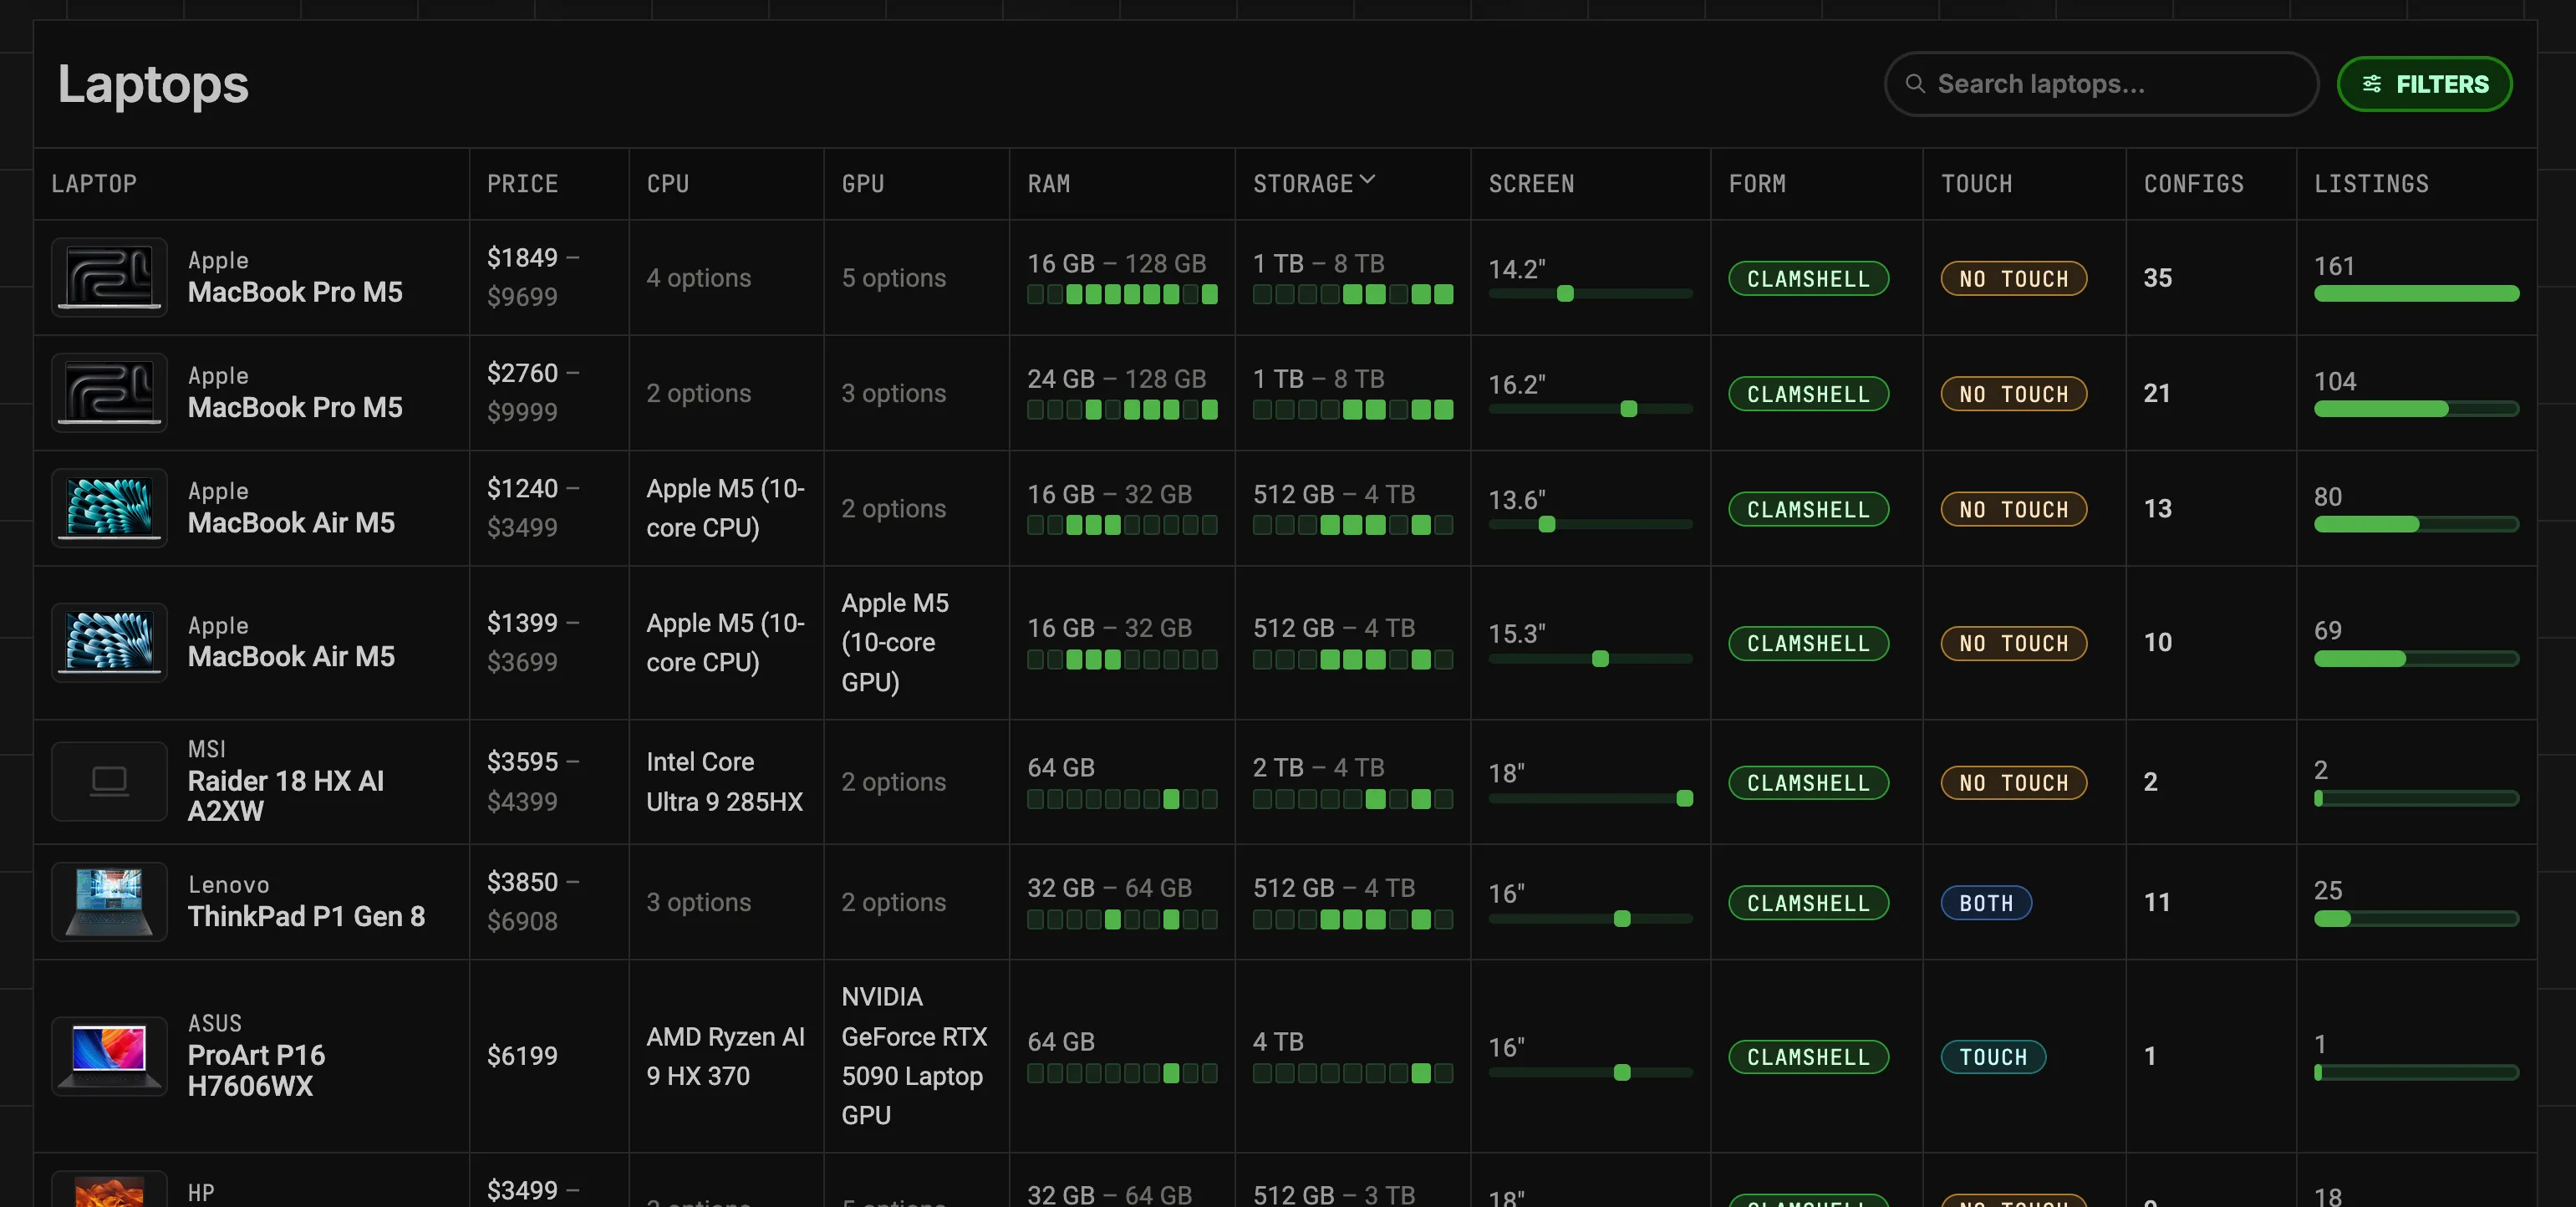
- explored several curated laptop-pick and comparison-table designs. not implemented
- added
llms.txt overview for ai crawlers
- continued the incremental static frontend builder work
- upgraded astro version to allow incremental updates
- added postgres build-state tables, frozen gpu projection/manifest plumbing and durable clickhouse sync generations. incremental mode remains disabled
- verified crash recovery with an isolated 300,000-snapshot sigkill/restart rehearsal
- iterating on large refactor of how clickhouse works and its schema
- improving the remote codex development workflow. added safer fetch previews and staging, active-task updates, cleanup checks, a task-management tui and one-command local promotion
- improved the buildapc knowledge base workflow
- automated incremental multi-subreddit reddit downloads
- imported the latest buildapc data and refreshed the wiki
- added raw top-level comment search so reply agents can learn the tone of real discussions while keeping the knowledge base as the factual source
- improved crawler reliability and debugging
- fixed jw and msy parsing/pagination and made browser-debug sessions accurately show failed jw crawls
- added better proxy-health observability for recurring surfshark disconnects
- started prototyping a single-session ebay shard crawler to reduce repeated browser launches while preserving coupon and new-item decisions. it is not wired in yet
- tightened the ai deal agent’s value and description rules, then continued reviewing and publishing selected component deals